 Tarekkharsa
This plugin has no README in the catalog yet.
All plugins
lahja
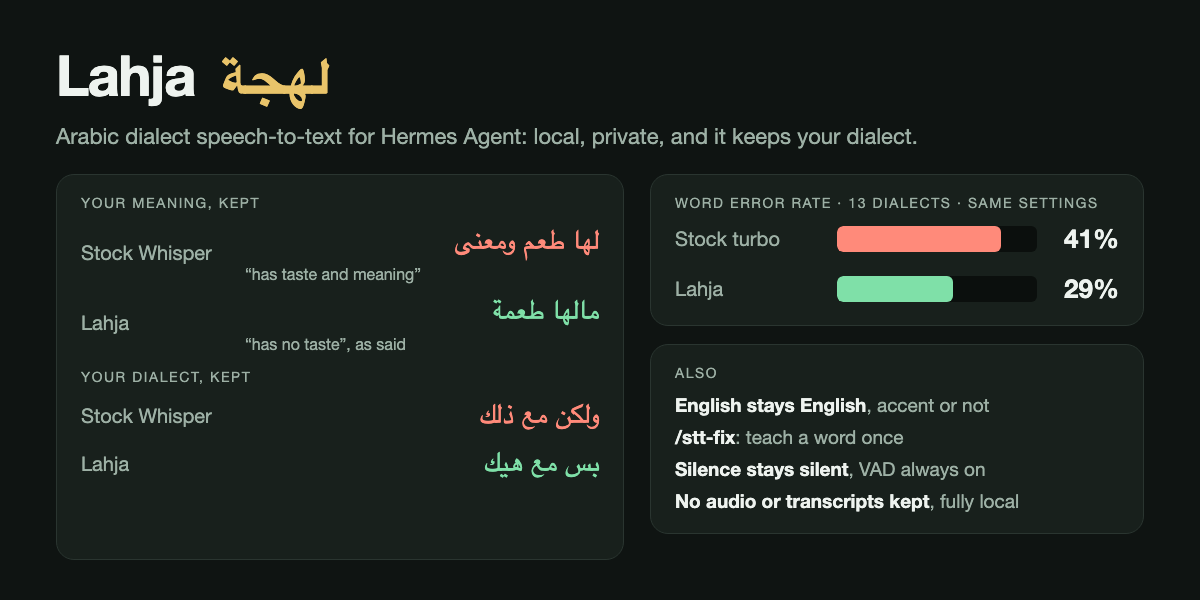
Arabic dialect speech-to-text (provider lahja), fully local: a dialect fine-tuned Whisper large-v3-turbo on whisper.cpp keeps Levantine, Gulf, Egyptian, Iraqi and Maghrebi speech as spoken instead of rewriting it as formal Arabic (WER 29% vs 41% for stock turbo with the same VAD, across 13 dialects), Silero VAD always on plus a filter for subtitle-credit hallucinations («ترجمة نانسي قنقر»), per-note language routing that never forces a non-Arabic language (English, including accented English the dialect model writes in Arabic letters, goes to a stock Whisper model you choose), and corrections taught once with /stt-fix. Disclosure — audio is decoded locally in a temp dir deleted after each call; nothing is uploaded. Network only in `hermes lahja setup`, which downloads commit-pinned, SHA-256- and size-checked model files from huggingface.co (redirected to its *.cdn.hf.co CDN); the dialect model is a community ggml mirror (JoaoZaokk) that bench/convert.sh reproduces byte for byte from oddadmix's official weights. Runs ffmpeg (local files only) and whisper-cli with a fixed argv, no shell, one deadline per note, at most max_parallel at once, and a minimal environment (PATH, LANG, LC_ALL, TMPDIR, LD_LIBRARY_PATH) without Hermes' variables. Reads the audio Hermes passes, its own model files, and an optional other_languages_model .bin you configure. Writes model files and the two phrases of each /stt-fix correction to its plugin data dir; corrections apply profile-wide and any user the gateway admits can add one (control/invisible characters refused, max 500). No audio or transcripts stored; no tools, hooks, background processes, telemetry or credentials.
About
Arabic dialect speech-to-text (provider lahja), fully local: a dialect fine-tuned Whisper large-v3-turbo on whisper.cpp keeps Levantine, Gulf, Egyptian, Iraqi and Maghrebi speech as spoken instead of rewriting it as formal Arabic (WER 29% vs 41% for stock turbo with the same VAD, across 13 dialects), Silero VAD always on plus a filter for subtitle-credit hallucinations («ترجمة نانسي قنقر»), per-note language routing that never forces a non-Arabic language (English, including accented English the dialect model writes in Arabic letters, goes to a stock Whisper model you choose), and corrections taught once with /stt-fix. Disclosure — audio is decoded locally in a temp dir deleted after each call; nothing is uploaded. Network only in `hermes lahja setup`, which downloads commit-pinned, SHA-256- and size-checked model files from huggingface.co (redirected to its *.cdn.hf.co CDN); the dialect model is a community ggml mirror (JoaoZaokk) that bench/convert.sh reproduces byte for byte from oddadmix's official weights. Runs ffmpeg (local files only) and whisper-cli with a fixed argv, no shell, one deadline per note, at most max_parallel at once, and a minimal environment (PATH, LANG, LC_ALL, TMPDIR, LD_LIBRARY_PATH) without Hermes' variables. Reads the audio Hermes passes, its own model files, and an optional other_languages_model .bin you configure. Writes model files and the two phrases of each /stt-fix correction to its plugin data dir; corrections apply profile-wide and any user the gateway admits can add one (control/invisible characters refused, max 500). No audio or transcripts stored; no tools, hooks, background processes, telemetry or credentials.
More by Tarekkharsa
2 plugins by Tarekkharsa in the catalog.