itpartypattaya
hermes-dreaming
Nightly, deterministic memory consolidation ("dreaming") for
Hermes Agent, in the spirit of OpenClaw dreaming.
An agent's memory goes wrong in two quiet ways: useful facts never make it into durable memory, and
durable memory fills up with stale or duplicated entries until the char limit silently stops all
writes. Every night a Python script looks at what the agent knows and what people actually said, and
wakes the agent only when there is something to decide. The rules call no LLM and the script never writes
memory; the agent applies its proposals through the regular memory tool and reports in a few lines. An
optional cloud judge, off by default, can second-guess the rules' mention count — see
below.
Task outcomes and recorded explanations (3.6.0)
With holographic 0.20.0 or later, read how stored facts helped or failed a task, separately from their truth/trust:
python3 skills/dreaming/scripts/dream.py --memory-outcomes
python3 skills/dreaming/scripts/dream.py --memory-explain ATTEMPT_ID --memory-format text
Enable collection in the provider (experience: on; optional experience_trace: on). Add "task_outcomes": true
to dreaming.json to include count-only summaries in the normal nightly report. Default is off. No additional model
wakeup or network call is added, no correction text is copied into a lesson cache, and nothing automatically changes
trust, ranking or MEMORY.md. Revisions count as one active outcome per attempt; these remain agent reports.
The default is the configured profile store. A scoped store requires an explicit --memory-store already allowed by
chat_stores.promote_from; reports never join stores, and since 3.7.0 the JSON summary names its store ("store"). Old providers report unsupported and continue normal dreaming.
See docs/experience.md for retention, erase boundaries, JSON output and limitations.
How it works
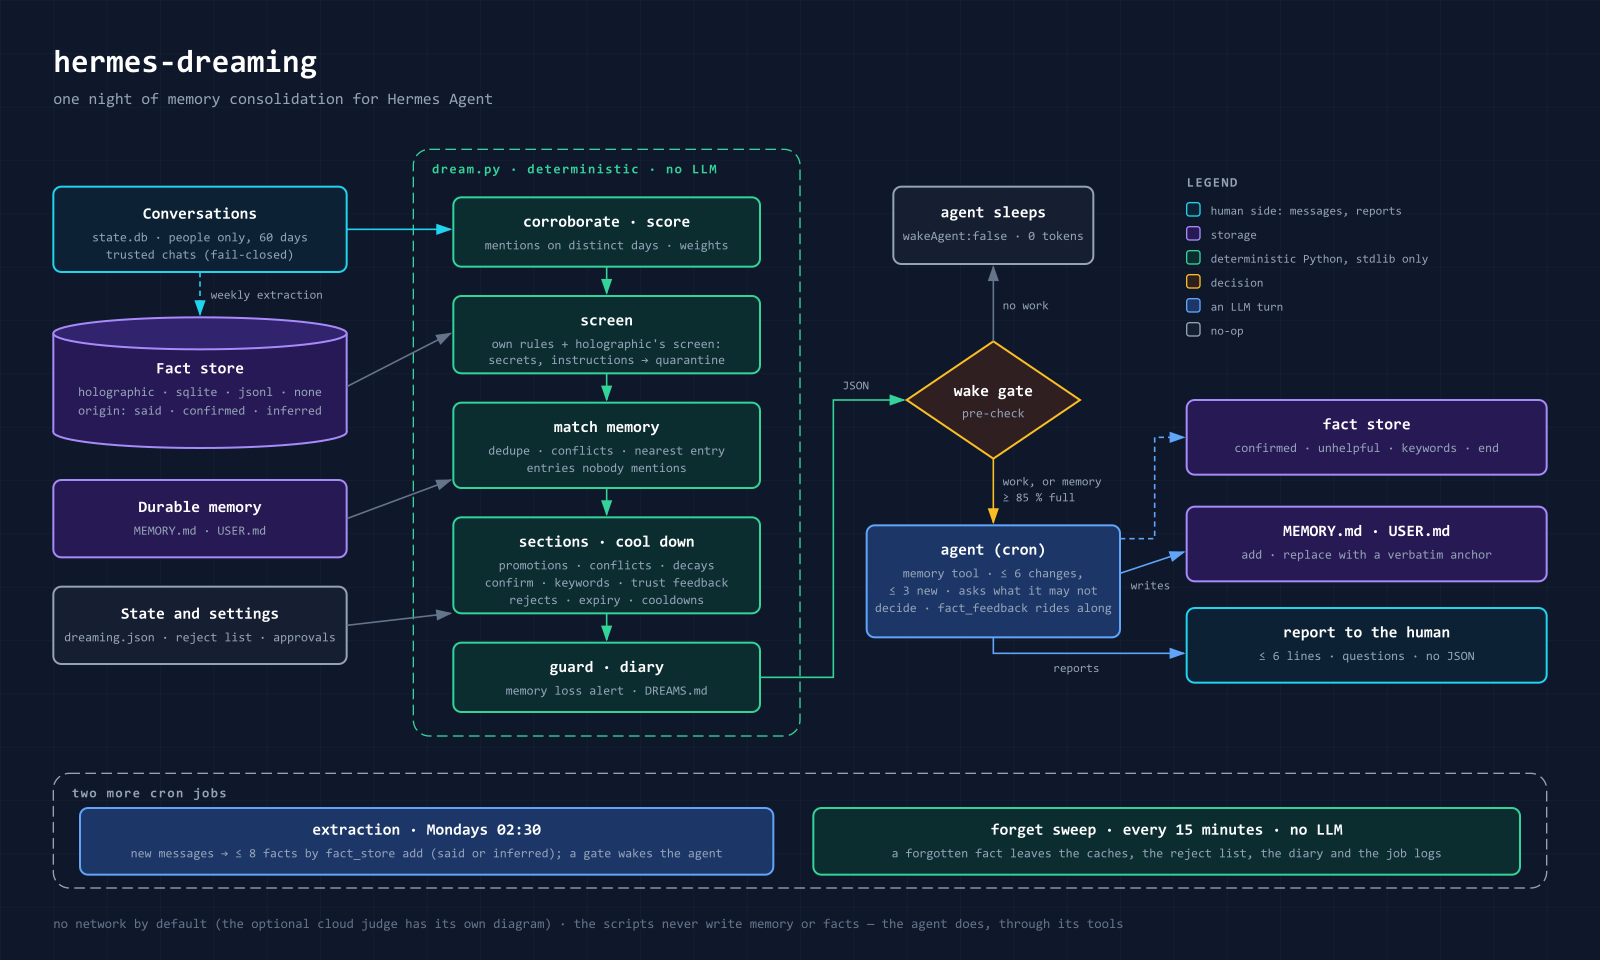
- Corroboration from real conversations. A fact counts only if humans mention it on distinct
days. Cron prompts, compaction banners, URLs, untrusted chats and the agent's own threads never
corroborate anything. Works in the languages the holographic store reads: Chinese, Japanese,
Korean and Thai are compared by character n-grams, Latin languages by stems without diacritics. - Scoring with the OpenClaw weights (relevance, frequency, diversity, recency, consolidation,
richness) plus a corroboration gate. - Matching against memory. Exact, declarative alias rules and stemmed containment in three
directions; a candidate that repeats an entry with different numbers is a possible update
(conflicts), not a duplicate. Every candidate carries the nearest entry, which file it lives in
and its full text, the source of the verbatim spanmemory patchchanges (Hermes ≥ 0.22), plus an
old_textanchor for thememory replaceof Hermes 0.21. - Screening. Secrets and prompt-injection are quarantined — by the dream's own rules and by the holographic
provider's screen (credentials in its 18 languages, token shapes, environment assignments, instructions in any
language), which the provider applies only to what it stores and recalls next — dated events expire (dates
and event words in 15 languages, from «14 de noviembre» to 11月14日), near-identical facts in the store reach the agent once. - A wake gate. On a quiet night the cron job prints
{"wakeAgent": false}and the model never
starts. A memory file close to its char limit counts as work (memory_pressure) — the limit gates
writes silently, so otherwise nobody notices until facts stop being recorded. - A loss guard. If a large share of memory disappears overnight, or a long entry loses half of itself, the
next report says so and names the entries that are gone. An entry the agent compressed, reworded, merged into
another one or split in two is not a loss: its words and numbers are still in the entries it wrote. - Feedback to retrieval. A fact you rejected keeps its trust in the fact store, so the
provider's prefetch goes on offering it. Such facts are listed with a ready
fact_feedback(unhelpful)call, so a rejection teaches retrieval too. - Confirmations (holographic ≥ 0.15.0). A fact people said again — on two different days, in messages that
hold most of its words and neither negate it nor give it a new number — is listed with a readyfact_feedback(confirmed)call: its trust
rises a little, and the agent's own conclusion counts as confirmed. Naming the topic is not saying it again, so
this is rare by design (none of 58 facts on a live family store; the loose rule would have offered 26). It never
wakes the model. Items also carry the fact'sorigin—said,confirmedorinferred(an agent's conclusion
nobody confirmed, asked about rather than written). - Keywords for search (opt-in, holographic ≥ 0.6.1). The fact store finds a fact by words it
does not contain only through its keywords — synonyms, other roots, translations. Facts without
them are listed a few a night (keywords_needed) with a readyfact_store updatecall, and the
extraction run gives keywords right when it adds a fact. Housekeeping: it never wakes the model.
Keywords and the provider's optional search by meaning (holographic ≥ 0.14) do different jobs:
meaning reaches a paraphrase that shares no words, but only while its endpoint answers; keywords
live in the store and work offline. The pass reads words either way — vectors are the provider's
business and never reach its JSON. - Duplicates across the store (holographic ≥ 0.19.0). Two facts that say one thing in other words — the
same thread described twice, a profile stored again by the nightly extraction — are found over the whole store
and asked about, one pair a night: «D-17: "…" and "…" — look like one fact. Merge?», both texts whole. Only a
"yes" to that number merges them, throughfact_store mergewith the versions you were shown; the copy's
history stays under the fact that remains. Nothing is merged at night, and pairs that differ by one word
(«утром» / «вечером»), a number, a person or a "not" are not asked about. The extraction run merges a retelling it
has just stored into the old fact itself, when the provider's hint offers it and nothing new is in it. - A diary (
memories/DREAMS.md) with provenance for every candidate.
Every item gets an outcome
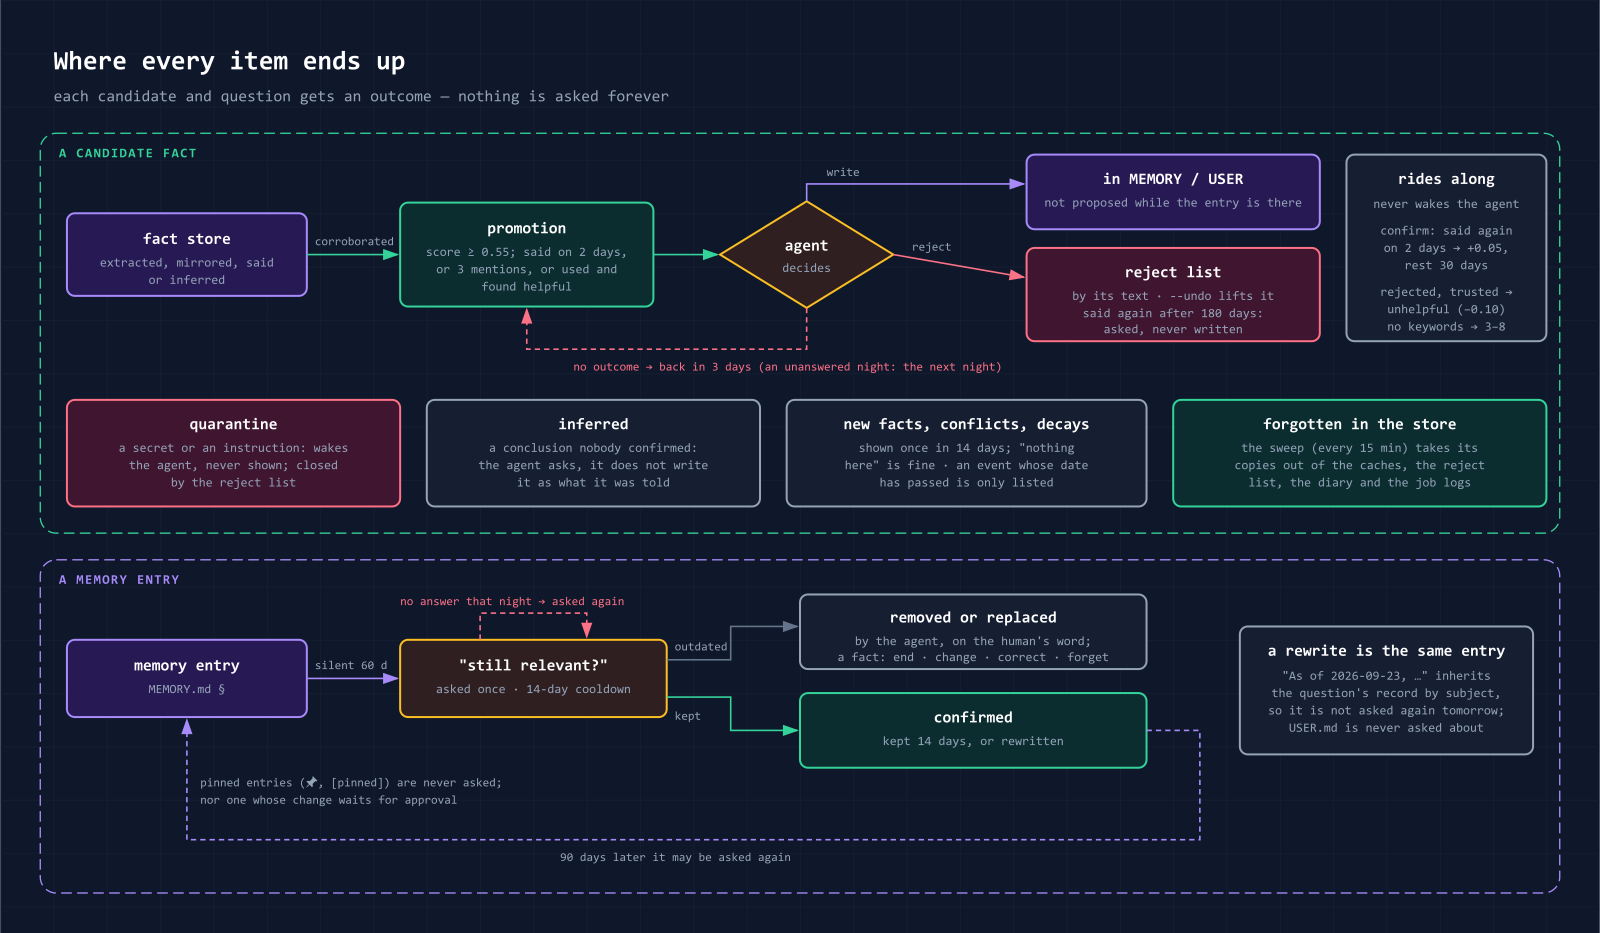
Nothing is asked forever. A promotion is either written or put on the reject list (matched by text;
dream-reject.py --undo lifts a rejection, and a fact people said again after 180 days comes back as a
question, reject_reask_days); with no outcome it comes back in 3 days. New facts, conflicts and decay
questions are shown at most once per 14 days. A memory entry that survived a "still relevant?" question — kept, or rewritten
in place with a fresh date — counts as confirmed and rests for 90 days. Cooldowns start only when
the agent actually answered: a night that failed halfway re-shows the same items.
With holographic ≥ 0.8.0 (stats.fact_history: true) a human's answer about a fact goes to the
store, which keeps the fact's history: "no longer true" → fact_store end, "it changed" → change,
"that was wrong" → correct, "forget it" → forget (final: the store's fact history goes too) plus removing the
memory entry that carries it. After a forget the store keeps only a tombstone — the id, never the
text — and this skill removes its own copies of the fact by that id: the last payload, the reject
list, the cooldowns, the diary lines (tagged [#<id>] since 2.4.0; older ones through an index of
line hashes kept while the fact still existed) and the logs of the dream cron jobs. Every pass does
that first; the no_agent job dream-forget-sweep.py does it every 15 minutes without the model.
This cleanup covers the store and the skill's own copies listed above. It does not rewrite Git commits,
external database dumps, system backups or Hermes session history. Those copies need their own cleanup process.
A report must distinguish successful deletion from the store from a retained external copy; a documented
history boundary is not removed by retrying the same sweep. The skill does not rewrite repository history.
A "merge?" question (holographic ≥ 0.19.0) has a number that is never reused. "Yes D-17" → fact_store merge
with the versions shown; a text that changed since makes the merge refuse (changed_since) and the question is
asked anew. "They are different" → dream-reject.py --not-duplicates D-17, never asked again (--undo D-17); with
no terminal in the session the pair simply rests 180 days. A question the agent's report did not name comes back the
next night. A merge is no forget: the diary keeps its lines, and only the skill's live state lets the copy go.
Install
Requirements: Hermes Agent ≥ 0.21, Python ≥ 3.9 (standard library only).
1. The plugin — a portable Agent Plugins v1 package (plugin.json + skills/dreaming/):
hermes plugins install hermes-dreaming      # the reviewed, pinned catalog entry
hermes plugins enable hermes-dreaming
Install from the catalog, not from a URL (see below). The cron jobs below are bound to this
plugin's own skill, so they run exactly the copy you installed (and the catalog reviewed). Plugin
skills are namespaced and kept out of the system prompt's skill index; the agent finds them with
skills_list and loads them with skill_view.
hermes skills install itpartypattaya/hermes-dreaming/skills/dreaming
The skill then lands in ~/.hermes/skills/dreaming/ and is listed in the skill index. The installer
scripts below use it only when the plugin is not installed; substitute that path in the commands.
2. The gates and the config
python3 ~/.hermes/plugins/hermes-dreaming/skills/dreaming/scripts/install.py
Hermes runs cron scripts only from ~/.hermes/scripts/ (a symlink is refused), so the installer
copies the three gates there, seeds ~/.hermes/dreaming.json from the example, does a dry run on
throw-away copies of the state, and checks the fact source and the core. It is idempotent;
install.py --check verifies without changing anything — run it after every update, since the copies
in scripts/ can drift from the skill. It also names a job Hermes will not fire: one due more than an hour ago
(the gateway is not running cron) or one with no next run. dream.py --nightly-status answers the short
question "is a night coming?" (read-only; the agent runs it when you answer a dream question).
== hermes-dreaming installer ==
  ✓ dream-precheck.py in place and identical to the skill copy
  ✓ dream-extract-precheck.py in place and identical to the skill copy
  ✓ dream-forget-sweep.py in place and identical to the skill copy
  ✓ config /home/you/.hermes/dreaming.json is valid JSON
  ✓ dry run: fact source: holographic · facts: 0 · human messages in window: 0
  ✓ core gives cron jobs memory natively (Hermes >= 0.21) — the extraction job can use fact_store
  ✓ memory provider 'holographic', fact store present (/home/you/.hermes/memory_store.db)
  ✓ holographic 0.17: cron jobs may write facts; forgotten facts are swept
  ✓ the fact store keeps origins and confirmations — items carry `origin`, the confirm section is on

== 9 ok, 0 warning(s), 0 problem(s) ==
3. Edit the config — the part nobody can do for you:
$EDITOR ~/.hermes/dreaming.json # timezone, trusted_chat_ids, agent_names, fact_source
Until trusted_chat_ids lists your group chats, no group chat corroborates memory (fail-closed
by design). If a trusted chat is a forum, list the threads that are not human talk — the agent's own
alerts, assistant bridges, machine-generated cards — under excluded_threads.
4. The cron jobs
~/.hermes/hermes-agent/venv/bin/python \
    ~/.hermes/plugins/hermes-dreaming/skills/dreaming/scripts/install_cron.py --deliver local --dry-run
# happy with the plan? run it again without --dry-run
The CLI has no flag for enabled_toolsets, and cron/jobs.json is live scheduler state, so job
creation goes through the Hermes Python API. The jobs get the plugin skill's qualified name
straight from Hermes' plugin registry (hermes-dreaming:dreaming on Hermes 0.22.6; earlier cores named
it agent-plugin-hermes-dreaming-<hash>:dreaming), so the plugin must be enabled first. When Hermes
renames it, a job bound to the old name runs without the skill: install.py --check reports a stale
skill binding, and install_cron.py --rebind points the job at the current name; all three gates likewise prefer the plugin's copy of dream.py. Re-running
install_cron.py updates existing jobs whose prompts exactly match a known shipped template for
that job's role. Local edits (even whitespace), missing prompts and unknown templates are preserved
with a warning: compare them with DREAM_PROMPT / EXTRACT_PROMPT in the installed script and
migrate them manually. No Git checkout or separate migration state is needed. A job that loads
another skill than this install provides is reported; --rebind also points it at the right skill
in place, preserving any other attached skills. Prompt synchronization does not require --rebind.
By default, schedules, delivery, model/provider, paused state and run counters are preserved.
Explicitly supplied settings that differ from existing jobs are reported. Add --update-existing
to apply only those supplied settings, for example --update-existing --model cheaper-model.
--inherit-model --update-existing clears both model and provider pins; it cannot be combined
with explicit model/provider values. Schedule changes support cron expressions to cron expressions;
Hermes may recalculate the next run and clear pending/quota scheduling state. No job is resumed.
--job-id <exact-id> limits the entire operation to that job, including prompt/rebind/settings
changes; missing jobs of other roles are not created, and a job of another role the installer cannot
classify or that runs in the wrong mode is reported without blocking the named one (a job of the same role
still blocks: both run the same gate script). Repeat it to select several jobs. Duplicates
are reported with their IDs and active count. Untargeted updates of duplicate roles are refused;
use explicit IDs to choose which jobs to maintain. Nothing is deleted automatically.
Use --upgrade --dry-run after updating the plugin, then repeat without --dry-run to repair copied
gates, synchronize jobs and run an independent final cron/gate check. All targets, config and arguments
are checked before gate writes; public Hermes schedule validation runs before apply. A direct invocation
without --upgrade refuses stale copied gates. This is staged work, not an atomic transaction: a
failure stops later writes, reports partial progress and can be retried. Use install.py --check
for the additional fact-source, memory and judge checks. --hermes-home <path> selects the same home
for files, the registry and cron API; choosing an interpreter alone does not choose a data home.
Use --dry-run to preview the actual creates and updates, including job IDs, changed fields and
the stock prompt diff. This reads a snapshot of cron/jobs.json without importing the cron API or writing
anything; it does not reserve that state for a later apply. Do not edit cron configuration at the
same time as running the installer: Hermes' public update API has no conditional update. The
installer re-reads before updating and skips edits it observes, but cannot close every race.
install.py --check reports outdated stock prompts as problems and custom/unknown prompts as
warnings. It also reports each role's execution mode, paused/terminal state and duplicates. Several
active jobs of one role or an incorrect execution mode are problems. Missing optional jobs and paused
jobs are warnings; a correct skill binding alone does not mean the job runs. --force explicitly
creates additional jobs, with a count warning; it is incompatible with targeted/rebind/settings updates.
Use
--deliver telegram:<chat_id>:<thread_id> to receive the report in a chat and
--extract-schedule "" to leave the extraction out. A third, no_agent job (--sweep-schedule,
every 15 minutes) cleans the dream's copies of facts the store has forgotten — no model, empty
output unless it removed something; --sweep-schedule "" skips it. Empty schedules skip this invocation
only: existing jobs remain enabled, and the installer names them. To pause future starts use
hermes cron pause <exact-id>; this does not cancel an execution already in progress.
To persist a smaller installation, set "cron": {"expected_roles": ["night", "sweep"]} in
dreaming.json. The allowed roles are night, extract, sweep; the default is all three, and []
deliberately expects/creates none. Installer and checker share this policy. Excluding a role does
not pause an existing job: one that is still active is reported. Invalid config is an error, never
an instruction to fall back to creating all jobs. No prompt/intent sidecar is needed.
The extraction job is cheap to run weekly — a
nightly run mostly answers [SILENT] on a small household.
A job keeps the skill name it was created with. The hash in it comes from the plugin's name in
plugin.json, so updates and reinstalls keep it. Disabling or removing the plugin does not: the job
then runs without its skill, and Hermes starts the nightly report with
⚠️ Skill(s) not found and skipped. install.py --check names such a job; re-enable the plugin, or
run install_cron.py --rebind against the install you kept. The check reads Hermes' plugin
registry, so run it with Hermes' interpreter (~/.hermes/hermes-agent/venv/bin/python) — a plain
python3 only gets a warning that it cannot tell.
Install from the catalog, not from a URL
hermes plugins install hermes-dreaming # the reviewed, pinned catalog entry
hermes plugins install itpartypattaya/hermes-dreaming installs HEAD as a custom, unreviewed
source, and the next plugins update does a git pull past the pinned SHA. Same code today,
different trust tomorrow.
Docker
In a container install the paths differ: the plugin lands under /opt/hermes
(or wherever HERMES_HOME points) and Hermes' own interpreter is
/opt/hermes/.venv/bin/python. Run the installers with that interpreter and as
the uid the gateway runs under — a docker exec as root would leave
cache/*.json owned by root, and the gateway's own pass then reads them as
missing. The scripts restore the previous owner when they can, but starting as
the right user is cleaner.
Upgrading from 2.0
2.0 bound the jobs to a regular dreaming skill. After installing the plugin, re-run step 2 (the
gates changed) and then step 4 with --rebind: the existing jobs switch to the plugin's skill without
losing their schedule, delivery or history.
Upgrading from 1.x
Version 1 was installed by cloning the repository straight into ~/.hermes/skills/dreaming. Version
2 keeps the skill in skills/dreaming/, so a git pull there would hide SKILL.md one level down.
Move the old clone away, install with step 1, re-run step 2 (the gates are replaced), and run step 4
with --rebind so the existing jobs point at the plugin's skill. Your config and state in ~/.hermes/cache/ stay as they are. The allow_memory
flag of 1.x jobs is unused since Hermes 0.21 and can stay or go.
Writes that wait for a human
If your Hermes runs with memory.write_approval: true, a write from a cron session answers
success: true, staged: true and the file on disk does not change: the entry sits in
pending/memory/ until you approve it. The pass reads that queue, so a candidate already waiting
is not offered again, an entry whose removal is queued is not asked about, and a queue that is both
large and old raises a pending_writes alert. Two things follow:
- the nightly report says "sent for approval", not "saved" — believe it;
- enabling the holographic provider for the fact store opens a second write channel that the
approval gate does not cover:fact_storewrites tomemory_store.dbdirectly, including
from cron, and its prefetch then feeds those facts into ordinary turns. With the gate on, consider
fact_source: none(the nightly memory review keeps working) —install.py --checksays this out
loud too.
Fact sources
The dream consolidates candidate facts; where they come from is fact_source in dreaming.json.
fact_source | where the facts are | extraction job | notes |
|---|---|---|---|
holographic (default) | the Hermes holographic provider's SQLite store (memory_store.db, or plugins.hermes-memory-store.db_path) | ✅ via fact_store | enable with memory.provider: holographic; use 0.8.0 or later — 0.2.0–0.7.x refuse every fact_store write from a cron job, so extraction and keywords store nothing (install.py --check warns). ⚠️ It left the Hermes core on 2026-10-11 (Hermes v0.21.7): hermes update installs the plugin itpartypattaya/hermes-plugin-holographic from the catalog in its place. The catalog entry may still pin an older release (0.6.1) — check with install.py --check; if that install failed and memory went off, see the plugin's README, "Memory went off after hermes update". With holographic scope: user / chat / thread the facts live in per-user / per-chat files the dream does not read by default and a cron job stores nothing — the report says so; see One database per chat. Nothing else about this skill changes |
sqlite | any SQLite table: fact_store_path, fact_table, fact_columns | — | for your own export; opened read-only |
jsonl | one JSON object per line: fact_store_path, fact_columns | — | the simplest export format |
none | no fact store | — | the memory files alone: "still relevant?", fill level, loss guard |
fact_columns maps your names onto id and content (required) and created_at, updated_at
(ISO or epoch), category, tags (string or list), trust (0..1). Example:
{"fact_source": "jsonl", "fact_store_path": "exports/facts.jsonl", "fact_columns": {"content": "memory"}}.
Hosted providers (mem0, Honcho, Supermemory, RetainDB) extract and deduplicate facts on their own
servers; reading them would need API keys in a cron job for little gain, so there is no adapter. If
you still want the dream's corroboration over them, export to jsonl.
One database per chat
holographic with scope: chat, thread or user keeps one database per chat (topic, user) — a bot that serves
many unrelated groups keeps them apart. Memory files are one for all chats, so the dream does not read those
databases unless told to, and then only in two steps:
"chat_stores": {"read": true, "promote_from": ["telegram:-1001234567890", "telegram:-1001234567890:42"]}
read— every database appears in the report as counts (facts, new ones): no text is read or shown, no ids.promote_from— the chats (topics withscope: thread, users withscope: user) whose facts join the pass. Each
is corroborated only by its own chat, and that chat's messages corroborate nothing else. Once a promoted
fact is written to memory, every chat sees it — list only chats where that is what you want. Withscope: user
the plugin files a fact by the turn's author, but Hermes keeps no author per message: a user's facts are
corroborated by the messages of that user's own sessions (in a group, the session owner stands for the author).
Such items carry store and ids like telegram--1001234567890#17; the agent writes them only through memory
(a cron session cannot reach a chat's database), and "forget it" is said in that chat. Extraction stays with the
shared store. The trust rules do not change: chats in trusted_chat_ids (and private chats, unless
trust_private_chats: false) still corroborate shared facts and memory entries — on a bot serving many unrelated
people, trust only the owner's chats.
Optional live task-outcome reports and recorded retrieval explanations (no second text cache or model calls):
docs/experience.md. These reports do not change trust or ranking.
Optional cloud judge (off by default)
The rules decide that a message mentions a fact when the two share enough words. That is cheap and predictable,
and often wrong: "Гоша тренирует юниоров" counted for "Гоша не пьёт кофе", a pasted report counted for every fact
it brushed against. On a frozen test set of 360 pairs, only 37 % of the pairs the rules counted were real
confirmations. Each false one pushes a fact towards memory or tells the store that people keep saying it.
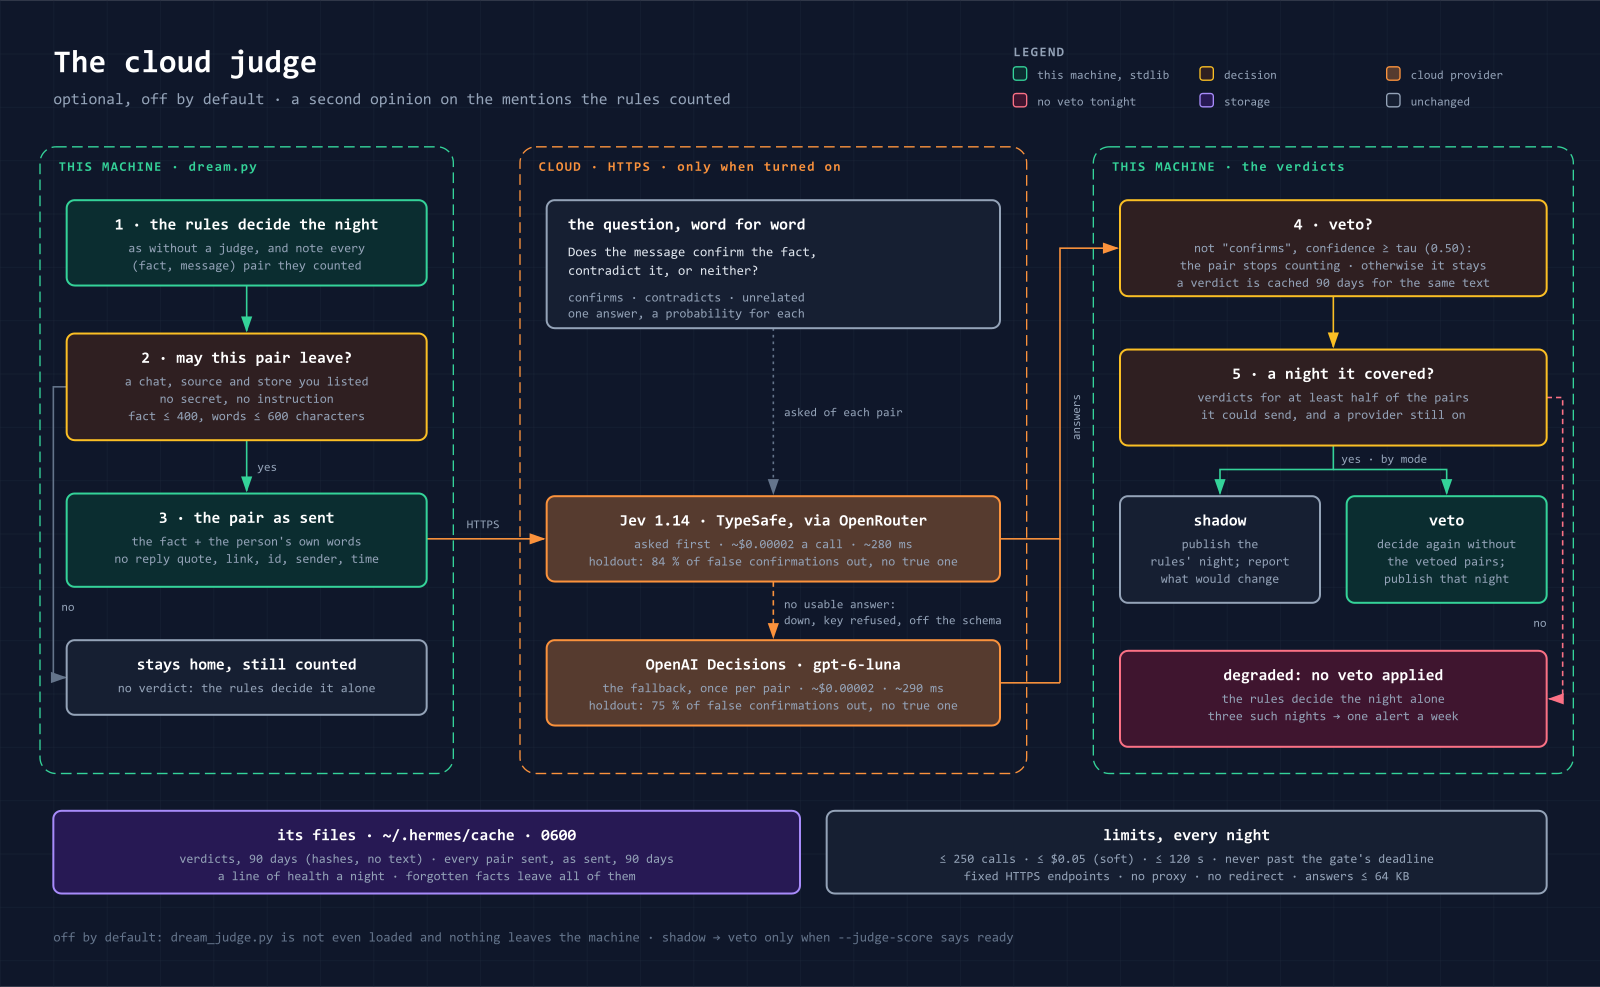
The judge is a second opinion on exactly those pairs. For every (fact, message) pair the rules counted, it asks a
decision model one question — does the message confirm the fact, contradict it, or neither? — and when the answer
is a confident "no", it takes the pair out of the count. It can never add a pair: what is a candidate is still the
rules' call, and a night without the judge is decided exactly as before. It is off by default; turned off, its
code is not even loaded and nothing leaves the machine.
How a night with the judge goes
-
The rules decide the night as always and note every pair they counted.
-
Each pair that may leave (see below) goes to the first provider: the fact's text and the person's own words,
nothing else, with this question and these three answers — the wording the threshold was measured with:Does the message confirm the fact, contradict it, or neither? confirms the message confirms the fact: the same person or thing, and the fact still holds contradicts the message contradicts the fact: it says the fact is not true or no longer true unrelated the message is about another person or thing, or neither confirms nor denies the fact -
The model picks one answer and returns a probability for each. An answer other than
confirmswith a
confidence of at leasttau(0.50 by default) is a veto. An answer that does not fit the schema is not used;
the pair goes once to the second provider, if there is one. -
In
shadowthe night publishes what the rules decided, and the report (stats.judge) says how many pairs the
judge vetoed and how many decisions that would change. Invetothe night is decided again without the vetoed
pairs, and that night is published — promotions, confirmations, fact decays, "said again" after a rejection,
new facts and conflicts, the evidence quoted. Memory-entry questions (md_decays) never take a veto. -
A night on which the judge answered for under half of the pairs it could send, or every provider was off,
applies no veto at all (effective: degraded). Three such nights without two good ones between raise one
judge_degradedalert a week, so a lost key or a dead network does not go unnoticed.
The models
A decision model is a classifier behind an API: it reads a text, chooses one of the answers it is given and returns
a probability for each. It writes no text, answers in a few hundred milliseconds and costs a fraction of a cent per
call. Two are supported; the first one listed in providers is asked first, the second only when the first gives
no usable answer.
Jev (jev) | OpenAI Decisions (openai) | |
|---|---|---|
| Made and served by | TypeSafe; served by OpenRouter (/api/alpha/decisions, an alpha API) | OpenAI (/v1/decisions, public beta since 2026-10-06) |
| Model | typesafe/jev-1.14 | gpt-6-luna |
| Key | OPENROUTER_API_KEY | OPENAI_API_KEY |
| Cost of one call, measured | about $0.00002 (OpenRouter reports the charge) | about $0.00002 (~210 input tokens at $0.10 per million; output is free) |
| Latency, measured (median / 95th percentile) | ~280 ms / 0.4–1 s | ~290 ms / ~0.4 s |
| False confirmations removed (holdout) | 84 % (142 of 169) | 75 % (127 of 169) |
| True confirmations removed (holdout) | none of 101 | none of 101 |
| Real confirmations among the counted | 0.37 → 0.79 | 0.37 → 0.71 |
| By language, false ones removed (ru / en / zh) | 76 % / 94 % / 85 % | 68 % / 87 % / 74 % |
| Data terms, as their documentation stated in October 2026 | not used for training; zero retention only for enterprise | kept up to 30 days for abuse monitoring; zero retention on approval; not used for training by default |
Jev comes first because it removed more false confirmations with the same zero errors; OpenAI is the fallback for
the nights Jev's alpha API is down or changes. Check the providers' current terms yourself before you send family
chats to them: what was sent cannot be recalled.
How it was measured: before any of this code existed, both providers answered 921 pairs prepared exactly as the
plugin prepares them — 561 to choose the threshold on, then a holdout of 360 written separately (by another model,
in Russian, English and Chinese) and frozen before the first run. tau 0.50 is the lowest value tried; the rule
was the lowest threshold with at most 5 % wrong vetoes and 10 % lost confirmations, and both providers met it
there. Before the release, the plugin itself replayed those recorded answers and vetoed the same pairs, one by
one. The whole measurement cost $0.023.
What it does not prove: the holdout was written by a model and not checked by a person, and live speech is messier
than written examples. shadow and a labelled sample (below) are how you find out on your own chats. Local models
were tried first, on the 3.2.0 experiment: Laya (multilingual, on a CPU) was the weakest of all, mDeBERTa-xnli was
better on its own but added almost nothing as a veto — hence a cloud option, off by default.
Turning it on
"judge": {"mode": "shadow", "providers": ["jev", "openai"], "send_from": "trusted", "send_sources": ["telegram"]}
Put the keys in ~/.hermes/.env — Hermes keeps provider keys out of the environment of cron scripts (and
terminal.env_passthrough refuses them), so the nightly judge reads its own line (OPENROUTER_API_KEY=…,
OPENAI_API_KEY=…) and no other; a key exported only in your shell works for a pass you run by hand, never at night.
A key is never printed, logged or written anywhere. install.py --check then shows the mode, where pairs may go and
whether the night has each key (a key only in the terminal it runs in is named as such), never its value. A section that breaks the schema turns the judge off and says why.
What leaves the machine
- Only from what you list.
send_fromis"trusted"(the trusted group chats and, with
trust_private_chats, private chats) or a list of chat ids;send_sourcesnames the session sources
(telegram, …);send_fact_storesnames promoted chat stores whose facts may be sent, with that chat's own
messages only;send_no_chat_sessionslets sessions without a chat go. The default lists nothing. - Only the fact and the person's own words. The fact's text as stored; the message without the reply quote,
with a voice transcript unwrapped, without links (with or withouthttps://) and[service brackets]. No ids,
senders or times. Names inside the texts do leave. - Nothing risky, nothing long. A pair whose text holds a secret or an instruction stays home, and so does a long
one (a fact over 400 characters, words over 600) — such pairs stay counted without a verdict. Long pasted messages
are a large share of what the rules count on a busy chat, and the judge does not see them. - To whom. OpenRouter for
jev, OpenAI foropenai; with both listed, one pair may reach both.
Limits, failures and files
- At most
max_attempts(250) calls,max_cost_usd($0.05, by the price the provider reports; soft — the last call
may pass it) and 120 seconds a night, never past the gate's deadline. HTTPS to fixed endpoints, no proxy, no
redirect, answers of at most 64 KB. A provider without a key, or that refuses it, is off until the next night. An
answer, cache or health file of the wrong shape is unusable, not fatal; anything else that fails inside the judge
leaves the night to the rules. - Its files, in
~/.hermes/cache/(0600):dream-judge.json— verdicts for 90 days, keyed by hashes, with fact ids
and no text, reused only for the same pair with the same text and a provider still listed;
dream-judge-journal.jsonl— every pair sent, as it was sent, and a record of each night, for 90 days, for your
review;dream-judge-health.json— one line a night;dream-judge-export-manifest.json— the last review sample,
until it is scored (90 days at most). A night with the judge off deletes the journal and the health file; the
forget sweep removes a forgotten fact from all of them, even with the judge off. - Off the network:
--dry-runreads the judge's cache and sends nothing;--explaindoes not load the judge;
--judge-replay FILEjudges from recorded answers (JSON lines{"provider", "fact", "words", "response"}) and
writes nothing of the judge. A real night — the gate,hermes cron run,dream.pywithout--dry-run— sends.
From shadow to veto
Run shadow for a couple of weeks, then take a blind sample: dream.py --judge-export sample.jsonl writes one
judged pair per fact, each line only {"id", "fact", "message"}. Label every line in a JSON-lines file
{"id", "label"} — S (confirms), C (contradicts), U (neither) or ? (for someone else to decide) — and run
dream.py --judge-score labels.jsonl. It answers ready when the upper 95 % bound of wrong vetoes is at most 10 %,
of lost confirmations at most 20 %, coverage at least 90 % and no wrong veto changed a decision; not_ready when
the lower bound of wrong vetoes is over 10 %; otherwise continue — label more. When the fallback gave over a fifth
of the verdicts, each provider has to pass on its own. Switch mode to veto only on ready.
Using it by hand
S=~/.hermes/plugins/hermes-dreaming/skills/dreaming/scripts
python3 $S/dream.py --dry-run                 # what tonight's pass would show; writes nothing
python3 $S/dream.py --explain 42              # why fact 42 scored like that
python3 $S/dream.py --forget-sweep            # clean the copies of facts the store has forgotten
python3 $S/dream-reject.py 42 --reason "thread was closed"
python3 $S/dream-reject.py --list             # what is muted, and how old
python3 $S/dream-reject.py --undo 42          # lift a rejection (by its key or the fact's id)
python3 $S/dream-reject.py --from-report --reason "duplicates the system prompt"   # after a manual cleanup
Cleaning durable memory by hand? Reject what you dropped: the facts stay in the store, flip to
in_memory: false, and the next pass would propose them right back.
A plain python3 may have no PyYAML. The scripts then read config.yaml with a narrow reader of their own. It
covers block key: value lines, comments and one-line {…}, and it does not guess. If it cannot read the
memory: block or the holographic plugin's block for sure, that block counts as unread:
- the pass reads no facts unless
fact_store_pathnames the store; - extraction stays off;
- the report and
install.py --checksay why.
Forms it leaves unread include a {…} over several lines, a value on the line after its key, tags, anchors and
block scalars (|). To read such a config, run the scripts with Hermes' interpreter
(~/.hermes/hermes-agent/venv/bin/python, which has PyYAML). The scheduled jobs always use it.
Verify it end to end
hermes cron list                          # the three jobs present and enabled
hermes cron run <dream job id>            # one real run
tail -20 ~/.hermes/memories/DREAMS.md     # a section for today
A quiet night prints {"wakeAgent": false} and the agent never starts — the wake gate doing its job.
hermes cron run and the gates are a real night, like dream.py without --dry-run: they write the state,
mark what they showed and, with the cloud judge on, send pairs to its providers. To look without consequences,
use dream.py --dry-run.
Configuration
~/.hermes/dreaming.json (or $DREAM_CONFIG); see skills/dreaming/examples/dreaming.example.json.
Missing file → defaults. A file that is there but is not valid JSON stops the nightly pass and the extraction job
with dream_error, instead of a night on the defaults (no trusted chats, so a batch of wrong "still relevant?"
questions and an extraction cursor moved past every group message); --dry-run and install.py --check still read
past it and say so. Precedence: CLI flag > DREAM_* env > config > default.
| field | meaning |
|---|---|
timezone | IANA zone for the diary date and day-bucketing of mentions. Not set → Hermes' own timezone, then UTC |
trusted_chat_ids | group chats whose messages corroborate memory (fail-closed: empty = none) |
excluded_threads | threads of a trusted chat that must not corroborate — {"<chat_id>": ["<thread_id>", …]} |
untrusted_sources | session sources that are machine prompts — cron, subagent and tool are always excluded; add cli when scripts drive the agent |
exclude_patterns | regexes; a message whose text matches never corroborates (bridge briefs, forwarded digests — machine text with no source of its own) |
trust_private_chats, trust_sessions_without_chat | whether a DM, and a session with no chat metadata, count as human speech (both default true) |
agent_names, extra_stopwords | noise words for the tokenizer |
alias_rules | declarative "same fact, other words" rules — {"fact": [["a","b"],["c"]], "memory": [["x"]]} |
fact_source, fact_store_path, fact_table, fact_columns | where candidate facts come from (above). Env: DREAM_FACT_SOURCE, DREAM_FACT_STORE |
durable_memory_paths | files that already are memory (dedupe targets) |
memory_char_limits | char limits of MEMORY.md / USER.md. Leave it out and the limits are read from Hermes' own memory.memory_char_limit / user_char_limit; the example's numbers are the core defaults and will misreport an install that raised them |
pending.dir, pending.alert_min, pending.alert_days | the approval queue (pending/memory): when ≥alert_min writes have waited longer than alert_days, one alert is raised |
pinned_markers | entries with these markers are never asked about |
probes | phrases that must stay in MEMORY.md / USER.md (["allergic to peanuts"]); when one disappears — by its text, or every word of it in one sentence of an entry in any form — one probe_missing alert. The loss guard catches a mass loss; this catches the one entry merged away while memory was tidied at its limit. Empty by default |
reject_reask_days | a rejected fact (dream-reject.py) is asked about once more when the rejection is older than this (180 days) and the fact was said again since — a new store row and a human mention after it; the item carries previously_rejected. 0 = never |
windows, gates, weights | scoring knobs — references/scoring.md; gates.md_confirmed_cooldown_days (90) is the rest period of a confirmed entry |
precheck.memory_full_pct | fill level (%) at which a memory file alone wakes the agent (default 85; 0 disables) |
precheck.timeout_sec | how long the gate waits for dream.py before reporting dream_error (default 600) |
corroboration.memory_mb | what one nightly pass may keep of what it read from the window's messages, in MiB (default 256, at least 1; an estimate on the high side). Past it the parts cheapest to read again are let go and read again when a fact needs them — a slower night, the same decisions. Lower it on a small machine; raise it if a large window makes the night slow — references/scoring.md, "Each message is read once a pass" |
extract.* | extraction chunking: max_messages 200, max_chars 40000, min_messages 15, backfill_days 60, max_retries 3 |
diary.heading, diary.keep_sections, diary.path | diary header, rotation and where it lives (memories/DREAMS.md) |
memory_loss_alert_fraction | loss-guard threshold (0.25) — applied to the share of lost entries and of lost characters |
gates.promotion_cooldown_days | rest for a promotion already shown (3 days); without it a candidate the agent could not write came back every night |
duplicates.enabled, .min_containment, .per_night, .question_cooldown_days, .max_pair_checks, .max_chars | the "merge?" questions (holographic ≥ 0.19.0, on by default): the share of the shorter fact's words the other must hold (0.7), questions a night (1), rest of an asked pair (180 days), the night's budget of pair checks (200 000; past it the search is skipped with one alert), facts longer than this (2000) take no part — references/scoring.md, "Duplicates across the store" |
keywords.enabled, keywords.cap | list facts without keywords for the agent (keywords_needed, at most cap a night, default 10) and ask the extraction run for keywords. Off by default; turn it on with holographic ≥ 0.6.1 — an older provider ignores the parameter, and 0.6.0 re-dated a fact when it got keywords |
chat_stores.read, chat_stores.promote_from | holographic scope: user / chat / thread only: list every per-chat database (counts), promote the facts of the listed chats — see One database per chat |
judge.mode, judge.providers, judge.tau, judge.send_*, judge.max_attempts, judge.max_cost_usd | the optional cloud judge: off (default) / shadow / veto; jev and / or openai, the first asked first; the veto threshold, 0.50–1 (default 0.50); what may be sent — send_from ("trusted" or chat ids), send_sources, send_fact_stores, send_no_chat_sessions; the night's limits (250 calls, $0.05). A section that breaks the schema turns the judge off and says why — see Optional cloud judge |
Safety and privacy
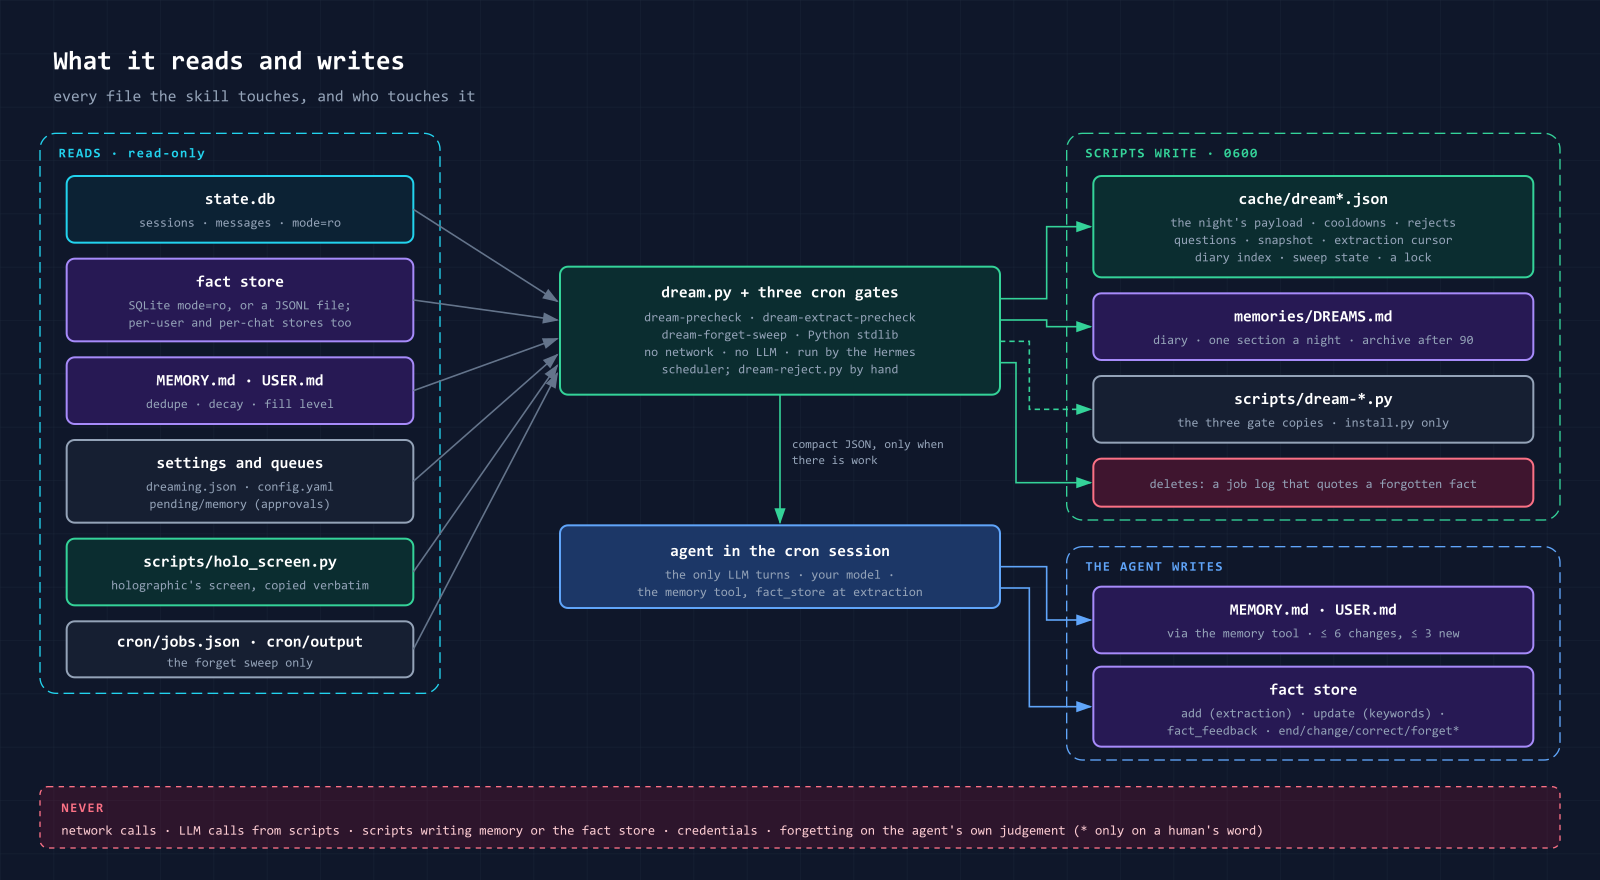
- Network: none by default. With the cloud judge on, the pass sends
what its section lists to OpenRouter and / or OpenAI over HTTPS, and nothing anywhere else. LLM calls: none
from the scripts besides that judge's decision call; the only model turn is the agent in the cron session,
with your model and your tools. - Reads:
state.db(sessions and messages, opened read-only), the fact store (read-only, per-user
and per-chat stores too), the memory files,dreaming.jsonandconfig.yaml, the approval queue
(pending/memory),scripts/holo_screen.py,dream_lang.pyanddream_yaml.pynext to it; the forget
sweep alsocron/jobs.jsonand the dream jobs' logs; with the judge on, its keys' own lines in.env
(nothing else of it). - Script writes:
~/.hermes/cache/dream*.json(the night's payloaddream.json, cooldowns, questions,
reject list, snapshot, extraction cursor, diary index of line hashes, sweep state; with the judge on, its
dream-judge*files; mode 0600) and a lock
file,~/.hermes/memories/DREAMS.md(diary; after 90 nights the older sections move to
DREAMS.md.archive.md), and — onlyinstall.py— the three gate copies in~/.hermes/scripts/(0755)
plus a seededdreaming.json.
A state file is written whole or not at all (a temporary file renamed over it). One that is there but is not
valid JSON is never read as "no state": it is moved aside to<file>.corrupt-<UTC time>with a warning in the
job's log, and the pass runs without it — look there if rejections or cooldowns seem to have reset.
Only a run that holds the state lock moves a file aside;dream-reject.py --listreports a broken list and leaves
it as it is.
The forget sweep rewrites those files without a forgotten fact and deletes the dream jobs' own logs
in~/.hermes/cron/output/that mention it, by its id or its verbatim text. The set-aside*.corrupt-*copies
cannot be parsed, and a write cut short may have cut the fact's text anywhere, so the first sweep after a
forgetdeletes all of them; later sweeps delete a copy that mentions a forgotten fact. A copy it cannot delete
is an error: the gate fails and the next run deletes it. Nothing else. - The agent writes memory entries through the
memorytool (at most 6 changes a night, of them at
most 3 new); in the extraction job, candidate facts throughfact_store add; keywords through
fact_store update; trust throughfact_feedback(unhelpfulfor a rejected fact,confirmed). The
skill deletes nothing from the store; a fact changes or leaves it throughfact_store end/change/
correct/forget, on a human's own words only. - Message and fact contents are treated as data, never as instructions. Facts, the evidence quoted
next to them, the messages the extraction job hands over and the "still relevant?" previews are
all screened for credentials and injection directives; a hit is quarantined (a secret's text is
published nowhere, an injection keeps a 60-char preview in the full JSON only).
The screening is a regex filter, not a guarantee: it knows the common key shapes
(sk-,gsk_,ntn_,gho_, AWS, Google, Slack, Telegram, JWT, PEM), credential markers in
Russian and English, and the injection phrasings the core's own cron scanner looks for, plus the
holographic provider's screen (scripts/holo_screen.py, a verbatim copy, MIT) — a
wording nobody has seen yet can still get through. Keep the approval gate on if that matters.
No tools, hooks, middleware or environment variables are registered. DREAM_SCRIPTdecides what code the gates run. Set in the environment of the cron jobs, it points all three
gates at anotherdream.pyinstead of the plugin's reviewed copy. It exists for unusual layouts
(skills.external_dirs); leave it unset otherwise.
Repository layout
plugin.json                          Agent Plugins v1 manifest
skills/dreaming/
  SKILL.md                           agent instructions
  scripts/dream.py                   the pass (never writes memory)
  scripts/dream_lang.py              stopwords, months, weekdays and dates of every language read
  scripts/dream_yaml.py              config.yaml reader for a run without PyYAML
  scripts/dream_judge.py             the optional cloud judge (loaded only when it is on)
  scripts/holo_screen.py             the holographic provider's screen, a verbatim copy
  scripts/dream-precheck.py          nightly wake gate        → ~/.hermes/scripts/
  scripts/dream-extract-precheck.py  extraction gate          → ~/.hermes/scripts/
  scripts/dream-forget-sweep.py      no_agent forget sweep    → ~/.hermes/scripts/
  scripts/dream-reject.py            reject list CLI
  scripts/install.py                 installs and verifies the gates
  scripts/install_cron.py            creates jobs and synchronizes recognized stock prompts
  scripts/cron-prompt-history.json   per-role SHA256 allowlist of shipped prompt templates
  references/scoring.md              signals, gates, sections, state files
  references/cron-memory.md          what cron sessions may touch
  examples/                          config and cron job examples
  tools/vendor_screen.py             makes holo_screen.py from the provider's source
tests/                               stdlib unittest, synthetic data, no network (the judge's: a fake provider
                                     on 127.0.0.1)
docs/                                README images (SVG sources in docs/src/)
Development
python3 -m unittest discover -s tests -v
The tests also run from a copy that keeps tests/ next to the skill directory. CI also runs
ruff check --select E,F,BLE --ignore E501 skills tests, and checks scripts/holo_screen.py against the provider's
source at the commit the copy names. tests/evals/evals.json holds scenario prompts for checking the agent's
behaviour against SKILL.md with skill-creator; CI does not run them. Issues and pull requests are welcome.
Design notes
- Corroboration must come from humans; machine text never counts.
- Every candidate needs an outcome. What the agent cannot close at night (there is no terminal
in the cron session) is closed by cooldowns on the script side, not by agent discipline. - Text, not ids. SQLite reuses ids; state is keyed by a text fingerprint, so a re-extracted fact
is recognised. - Zero writes is a success. A night is capped at 6 memory changes, and an entry is changed only
with text the script hands over verbatim. - Borrowed ideas: OpenClaw (phases, weights, gates, loss fraction, explain), mem0 (nearest entry →
update instead of append), Graphiti (supersession as a flag), Generative Agents (evidence
citations), MemoryBank (decay by strength).
Author
Anton Vaskov — Telegram @passone, GitHub itpartypattaya.
License
README from the reviewed commit 21878d3; it updates when the author re-pins.