Cloudflare Workers AI provider for Hermes
Use Cloudflare Workers AI models in
Hermes Agent as a first-class provider: pick
Cloudflare Workers AI in hermes model, or run hermes chat --provider workers-ai -m @cf/openai/gpt-oss-120b.
An independent community plugin, not affiliated with Cloudflare.
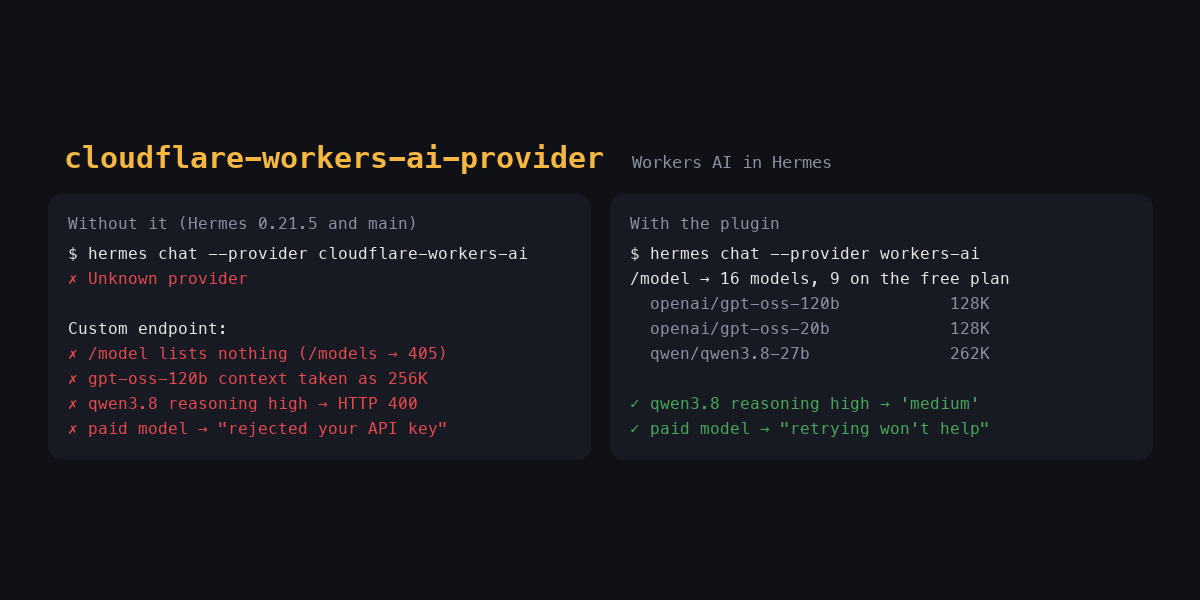
Why a plugin?
Measured on 2026-09-29 against Cloudflare's live API on the Workers Free plan, with Hermes v0.21.5 and
main:
| Without the plugin | With it | |
|---|---|---|
| Choosing Workers AI as a provider | Unknown provider 'cloudflare-workers-ai' |
Listed in hermes model |
| Model list, through a custom endpoint | Empty: Cloudflare's OpenAI-compatible /models answers HTTP 405 |
The 16 Workers AI models that have function calling and at least 64K of context |
| Context window, through a custom endpoint | gpt-oss-120b is assumed to have 256K (it has 128K), so Hermes compresses too late | Cloudflare's own values, 128K to 1.3M |
qwen3.8-27b with reasoning high, through a custom endpoint |
The turn fails: HTTP 400 Unexpected reasoning effort high. Supported types are xhigh (default), medium, and low |
Sent as medium |
| A paid-plan model on the free plan | "custom rejected your API key … Update it" | "Cloudflare Workers AI rejected the request and retrying won't help. Pick another model", followed by Cloudflare's "not available on the Workers Free plan" |
Install
hermes plugins install cloudflare-workers-ai-provider
In the Cloudflare dashboard, open AI → Workers AI → Use REST API. It shows your Account ID and
a Create a Workers AI API Token button. Then choose Cloudflare Workers AI in hermes model: it
asks for the token and then for the base URL, which is
https://api.cloudflare.com/client/v4/accounts/<your account ID>/ai/v1, and saves both to
~/.hermes/.env. You can also add them there yourself, with the account ID written out (Hermes does not
expand ${...} in .env):
CLOUDFLARE_WORKERS_AI_API_TOKEN=<your token>
CLOUDFLARE_WORKERS_AI_BASE_URL=https://api.cloudflare.com/client/v4/accounts/<your account ID>/ai/v1
The plugin uses its own variable names so that a Cloudflare Pages token in CLOUDFLARE_API_TOKEN
(which Hermes' publish-site skills use) is never sent to Workers AI. To pick the model in
~/.hermes/config.yaml instead of hermes model:
model:
  provider: workers-ai
  default: "@cf/openai/gpt-oss-120b"
Models
From Cloudflare's model catalog on 2026-09-29: the models with function calling and at least 64K of context. The Workers Free plan includes 10,000 Neurons a day; the last seven models need Workers Paid.
| Model | Context | Vision | Reasoning effort sent | Plan |
|---|---|---|---|---|
@cf/openai/gpt-oss-120b, @cf/openai/gpt-oss-20b |
128K | low, medium, high | Free | |
@cf/qwen/qwen3.8-27b |
262K | ✓ | low, medium, xhigh | Free |
@cf/zai-org/glm-4.7-flash |
131K | — | Free | |
@cf/google/gemma-4-26b-a4b-it |
256K | ✓ | — | Free |
@cf/nvidia/nemotron-3-120b-a12b |
256K | — | Free | |
@cf/meta/llama-4-scout-17b-16e-instruct |
131K | ✓ | — | Free |
@cf/mistralai/mistral-small-3.1-24b-instruct |
128K | — | Free | |
@cf/ibm-granite/granite-4.0-h-micro |
131K | — | Free | |
@cf/deepseek-ai/deepseek-v4-flash-0731 |
1.3M | none, low, high, max | Paid | |
@cf/deepseek-ai/deepseek-v4-pro-0813 |
1M | none, low, high, max | Paid | |
@cf/moonshotai/kimi-k2.6 |
262K | ✓ | none, high | Paid |
@cf/moonshotai/kimi-k2.7-code |
262K | ✓ | — | Paid |
@cf/zai-org/glm-5.2 |
262K | none, high, max | Paid | |
@cf/zai-org/glm-5.3, @cf/zai-org/glm-5.3-flash (vision) |
1.3M | low, high, max | Paid |
Reasoning effort follows Hermes' own rule. A level the model does not list goes to the nearest weaker
level it does list. A level below the model's lowest goes to that lowest level. With reasoning turned
off, a model that lists none gets none, and any other model gets its lowest level: gpt-oss always
reasons, qwen3.8 would otherwise run at its xhigh default, and Cloudflare's catalog says glm-5.3 turns
none into max.
Models marked — get no reasoning_effort field. With no reasoning effort configured, nothing is sent
and the model uses its default. The free-plan values were checked against the live API; the paid-plan
values come from Cloudflare's catalog.
Security and footprint
- Registers one model provider,
workers-ai, when Hermes loads it. No tools, hooks, commands or background threads. - Network: chat requests go to the URL in
CLOUDFLARE_WORKERS_AI_BASE_URLthrough Hermes' own client, carryingCLOUDFLARE_WORKERS_AI_API_TOKEN. The plugin itself opens no connections. The model list and model details are built into the plugin, so nothing is fetched to show them. - Reads no files, writes no files, starts no processes and has no dependencies beyond Hermes. Hermes, not the plugin, reads the two variables, per profile.
Compatibility
Hermes 0.21.5 or newer. CI runs the tests against Hermes v2026.9.24 (0.21.5) and main every day.
Changelog
1.0.0
- The
workers-aimodel provider: the Workers AI models Hermes can run, with Cloudflare's context windows, per-model reasoning effort, and a clear message when a free-plan account picks a paid-plan model.